


Cutting delivery time on eight Shopify stores with AI agents and automated QA
Yepoda is a Berlin K-beauty brand founded in 2020. DigitalSuits has run the technical side of its Shopify storefronts since May 2021.
Our engagement runs on a retainer model, so we provide: a dedicated developer, a team lead, a project manager, a QA engineer, and a block of flexible hours.
In spring 2026, Yepoda's team approached us with a new request about the Agentic development trend. Agentic development was everywhere that year. Teams were posting about doubling their output, and they wanted to know whether the same thing could work here. Could AI take over more of the store's day-to-day operations, cut manual work, and lower the retainer cost?
It was the right question to ask. Instead of answering based on what was trending, we started by auditing the challenges to give an honest estimate of what agents could realistically take over.
Client
Country
Germany
Partnership period
June 2021 – Ongoing
Team
Shopify developer, Project manager, QA
Services
Technologies
Shopify, Shopify Plus, Liquid, HTML, JavaScript, Remix, Node.js, AWS, Vue 3, Vite, Pinia, Tailwind CSS, Laravel, PHP, MySQL, MongoDB
Nothing explained the store except the people who built it
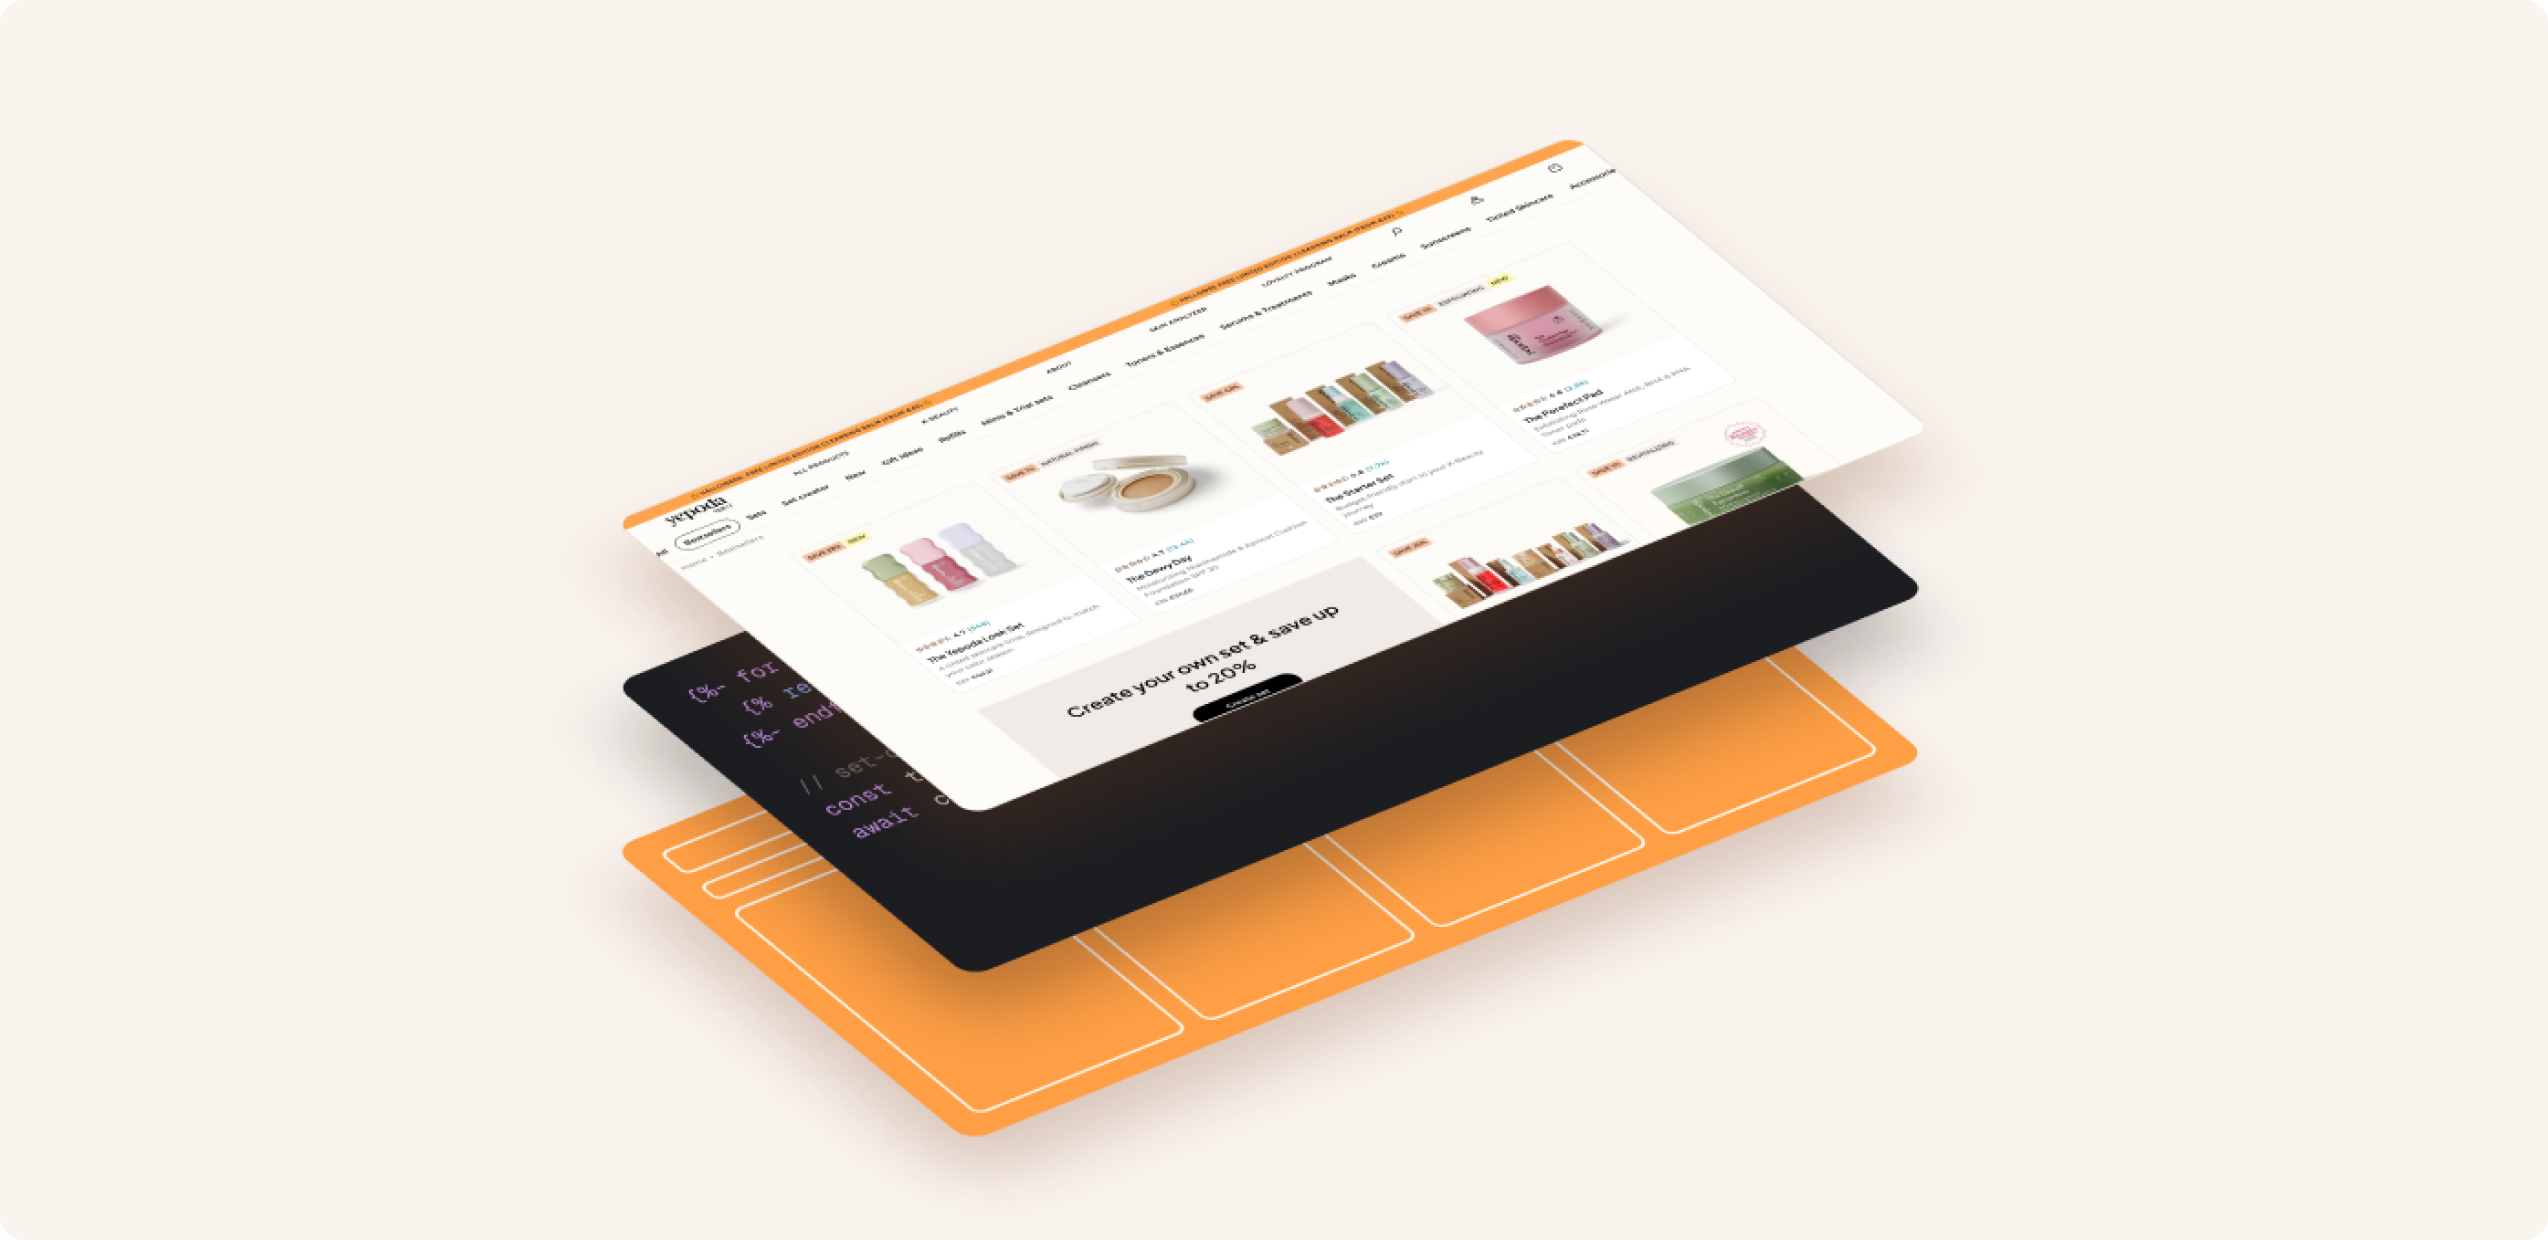
Agentic development is usually applied to new projects, where there’s no existing codebase, no live features to protect, and no customers affected if something goes wrong. Yepoda's store is the opposite case: five years old, seven repositories, eight live markets.
- Only the people who built it knew how it worked. A fully custom theme with six satellite applications around it. Backend-only repos expose API endpoints the theme calls over fetch, so the theme owns the interface while the app owns the logic and the data. Loyalty, checkout, and discounts all reach into each other, and most of those connections aren't visible from inside any single repository. Reviews appear as a few lines in the theme while most of the logic sits in a separate application.
- The ask needed defining before it could be scoped. Yepoda wanted AI handling more of what junior and middle engineers were handling, so running the store took fewer hours. But "AI manages the store" covers everything from merchandising and content to writing production code, and those are different projects with different risks.
- The riskiest code was the least documented. Five years of custom JavaScript for product pages, carts, and checkout, running in production and working, with little written down about why it was built that way or what depended on it. A small change could break something that had worked for years and directly affect customers placing orders.
- Documentation had drifted. Confluence held real knowledge accumulated over years, alongside pages describing features that had since changed and nothing at all about others. A missing page produces a question; a wrong page produces confident, incorrect work.
- Manual regression testing multiplied across markets. Every deployment needed the critical paths verified (discounts, cart drawer, product pages, collections) on every storefront, in every market.
What we built, and what we deliberately didn't
Yepoda wanted AI to take on more of the work behind its store. We agreed to focus on engineering: building new features and maintaining the existing system, which took up much of the team's time. Before agents could help, they needed to understand how the store worked. So we spent the first half of the project documenting the system and giving them that context.
We wrote down what only the team knew
Every one of the seven repositories was audited: tech stack, entry points, build process, how it deploys. More importantly, how it connects to the theme, where its entry and exit points are, and what breaks if those connections change.
Each repository then got its own CLAUDE.md, written in an order set by risk rather than convenience. We started with the theme, because the rest of the store depends on it. Checkout came next, since errors there carry the greatest business risk. Then loyalty, discounts, the shade finder, the contact form, and the reviews translator.
Each file covers what the repository does and why it exists, the architecture decisions behind it, how to run and deploy it, which files matter, and what not to touch without understanding it first. The two repositories that need a machine-readable index, yepoda-dev under tech-doc/, and yepoda-checkout-customization, also carry an llms.txt.
Once those were complete, we brought everything together in a master context file. It explains the system in plain language, including how the repositories connect and how releases work, and covers Shopify requirements such as theme versioning and app proxy setup.
The team's knowledge now lives in the repository, where new engineers and AI agents can both find it.
We mapped how the pieces work with each other
Documentation per repository doesn't help with features that span several, so the connections were documented in their own right. We listed every third-party API against the repository that calls it, along with the data flow and what happens if the API is unavailable, with particular attention to loyalty, checkout, and discounts, which all reach into each other.
The critical flows were drawn as sequence diagrams: how loyalty points are displayed, how points are awarded for subscriptions and reviews, how a discount is applied at checkout, and how a contact form submission is handled. Each shows which repository acts, what data passes between them, and what the expected outcome is.
An agent working on reviews now knows the translator application exists, goes and looks at it, and opens its pull request across both repositories.
The riskiest code got explained first
We worked through the custom JavaScript written over five years for cart, checkout, and product pages block by block, starting with the theme and following the same priority order. Each significant block got an explanation of what it does, why it was written that way, and what it affects.
Anything touching cart, checkout, or product pages went first, for the same reason it was flagged as the biggest risk in the first place.
Confluence was cleaned up rather than abandoned
Outdated pages were updated or archived, not deleted, since the history has value, and new pages were written for the features that had none. Every page that survived carries a 'last verified' date and a link to its repository, so the next person to read it knows how much to trust it.
Every change came from the gaps identified during the audit. The team focused on what actually needed fixing rather than rewriting things that already worked.
Agents got a defined boundary
What agents can do on their own is set out in three levels:
Level | What the agent does | Example |
|---|---|---|
1 | Works without review | Copy changes, minor CSS, text updates, image swaps |
2 | Implements, then shows the result to a human before it moves on | New Liquid sections |
3 | Needs human approval before acting | Checkout logic, API integrations |
Cross-repository conflicts follow a defined protocol rather than agent discretion.
The split follows cost of failure, not difficulty. An agent is perfectly capable of changing checkout logic – the reason it doesn't do that unreviewed is that a mistake there stops orders.
A team of agents, each with its own function
Rather than one general assistant, the project runs a few role-specific agents, each defined in its own file in the repository:
Development
- shopify-developer – Shopify platform work
- frontend-developer – theme and storefront
- backend-developer – the applications behind the theme
- yepoda-developer – the project orchestrator, it pulls the Jira ticket and carries Yepoda’s own conventions
Build quality
- section-architect – theme section structure
- pixel-perfect – build matches design
- performance-optimizer – speed and page weight
- qa-engineer – test coverage
Inputs and documentation
- figma-extraction – pulls design specs from Figma
- claude-md-writer – maintains the context files
- guide-writer – internal guides
- prompt-engineer – refines the agent definitions
A /create-task slash command sits at the front of the workflow. Ticket details are pasted into it, and it structures them into a task an agent can act on, pulling out any Figma links along the way. From there, yepoda-developer fetches the Jira ticket itself, and figma-extraction goes and gets the design data.
The preparation that used to sit between “ticket assigned” and “development starts” now mostly happens before a developer looks at it.
Regression testing stopped being manual
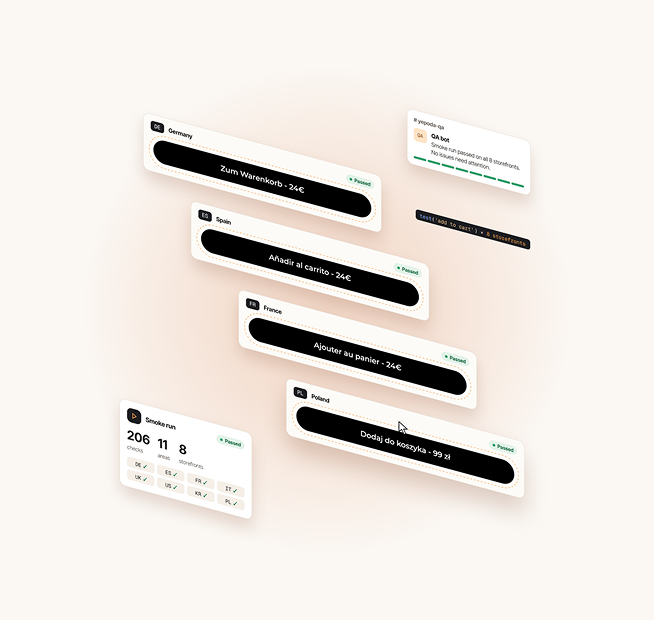
Yepoda told us which areas cost money when they break. That list became a Playwright suite covering 206 checks across 11 areas: the homepage, header and footer, search, discounts, the cart drawer, product pages, collections, free gifts, Set Creator, accessibility and speed. Full product-page coverage runs as its own job.
A smoke run over the critical paths takes 18 to 20 minutes. Anything that fails keeps its evidence (screenshots and video of the moment it broke), so investigation starts from the failure instead of trying to reproduce it.
New functionality is still tested by hand first. Only once it’s live and behaving does it get automated, which keeps the suite a safety net rather than a source of false confidence.
Results everyone can read
Runs are triggered from a GitHub Actions workflow and report into a Report Portal dashboard on our own server, split by market. That dashboard is built for a QA engineer, so results also go to a dedicated Slack channel showing which store was tested, what passed, what failed, and what needs attention.
Tests run against the live storefront, so what they check is what customers are actually using.
For Yepoda's own team, the change is where attention goes. Functional regression is covered, so their QA time moves to what a script can't asses: how a page holds up on a phone, whether an image is good enough, whether a layout breaks at an awkward width.
Same retainer with more work through it
Nothing changed for a shopper, which is the right outcome. What changed is how much effort sits behind the store.
This is now how we set up every project we run.
7 repositories documented
Every connection, entry point, and failure path written down, with the theme at the center.
Up to 20% less time on routine engineering work
Documentation, test cases, and requirements start as a draft instead of from a blank page.
10-15% faster delivery overall
Measured against how the same team estimated the same work before.
206 automated checks across 11 areas
From the homepage and search to discounts, free gifts, accessibility, and speed.
$29 a month, against roughly $1,000 of manual QA time
Checking eight storefronts by hand is about 34 hours a month at a QA engineer's rate.